Local web research · CLI & MCP
Web research on your computer. Evidence instead of raw pages.
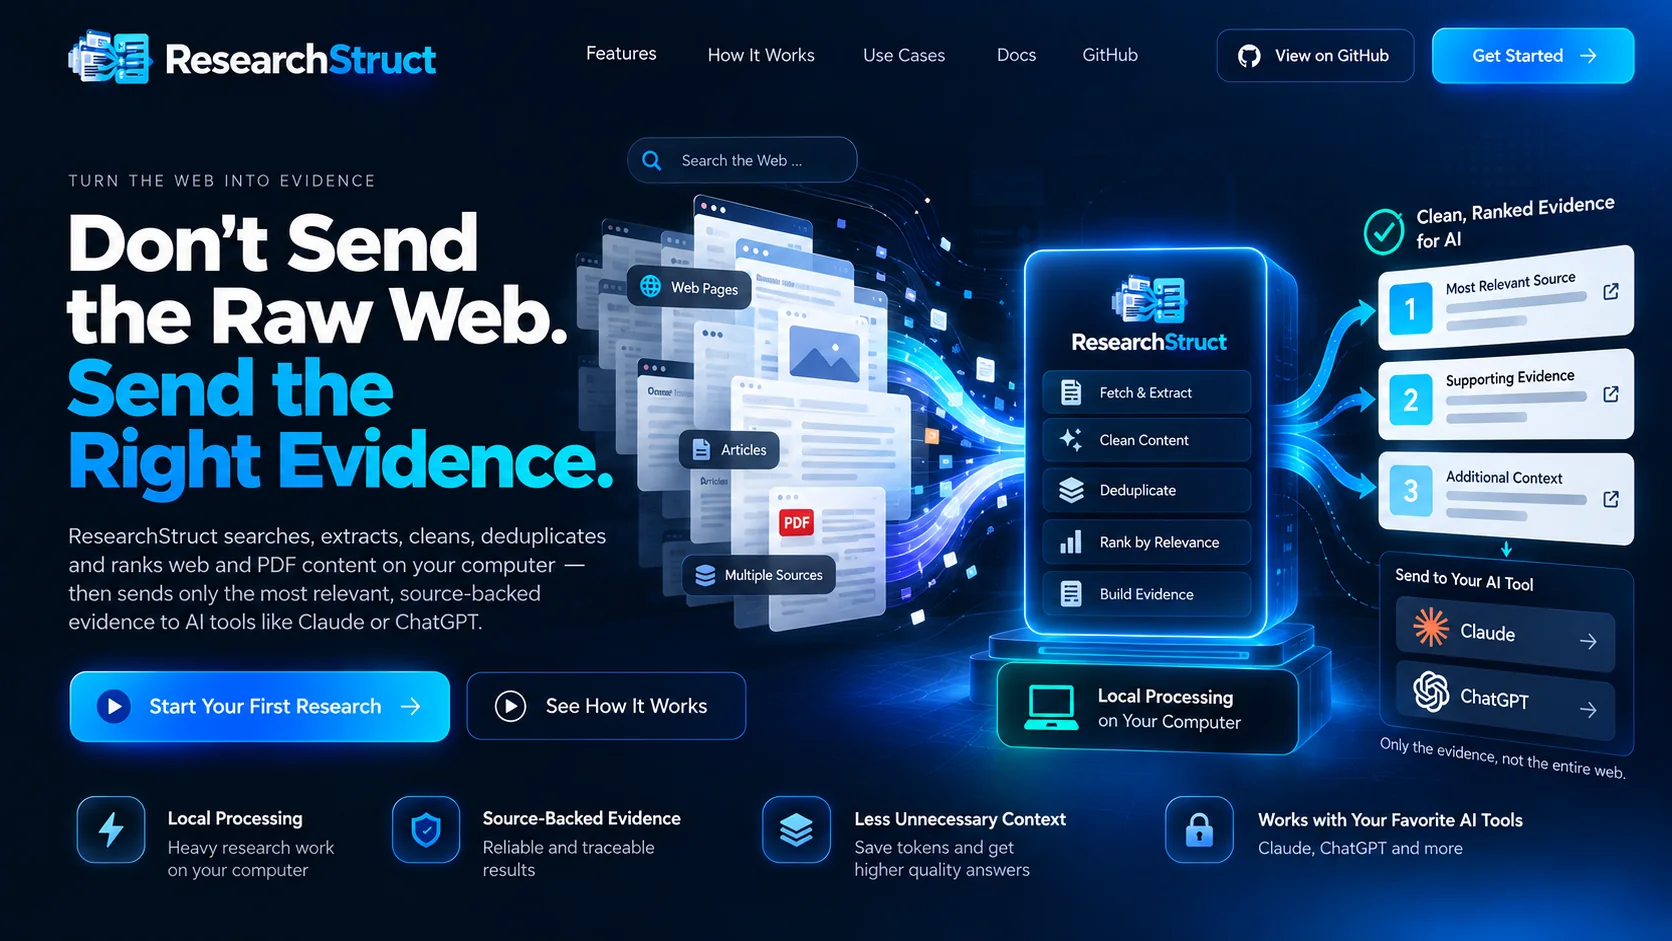
ResearchStruct searches the web, fetches pages and text PDFs, removes duplicates and ranks the passages locally. You or Claude get a small evidence pack with sources. No language model is involved in any of these steps.
Version 0.4.2 · MIT licence · Python 3.10+ · the repository is currently private.
- Python CLI
- Local MCP server
- No API key
- Source for every passage
What you get back.
-
Small, citable input
A run returns 8 to 25 ranked passages, each with its source URL and, for PDFs, the page number.
-
Deterministic ranking
BM25, TF-IDF, exact terms, headings, source quality and freshness, combined with fixed weights.
-
Honest about weak evidence
Warnings such as missing key terms or a missing official source are part of every result.
From a question to an evidence pack.
-
Ask
Give it a question or a URL, on the command line or through Claude.
-
Search & fetch
It runs a web search and downloads the pages and text PDFs it finds.
-
Clean & rank
Main content is extracted, duplicates are removed and passages are ranked.
-
Evidence pack
The best passages are written to a folder as JSON and Markdown.
Why ResearchStruct?
Reading whole web pages into a conversation costs context and buries the relevant lines. ResearchStruct does the collecting and ranking on your computer, so the assistant only sees what was selected.
- Runs locally: the only network traffic is the search and the pages it fetches
- One core, two front-ends: the CLI and the MCP server run the same pipeline
- Four MCP tools for Claude Code and Claude desktop
- A second command turns a whole document into structured records
Scope and limits.
ResearchStruct is pre-1.0 and maintained by one person. It is deliberately narrow.
- No OCR: scanned PDFs are reported and skipped
- No embeddings and no language model
- One search backend
- Not published on PyPI
Text returned from the web is treated as untrusted data, never as instructions.
Interested in ResearchStruct?
The repository is private for now. Write to me if you want to try it or use the same approach in your own project.